

On a long ride, you learn more about a bike on the steep climb than on the smooth stretch. AI agents deserve the same kind of test before a company lets them handle customer relationships, forecasts or a crisis. Firmulate’s live experiment puts models in charge of a small software company and makes their decisions visible.

Get sports gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A business under pressure
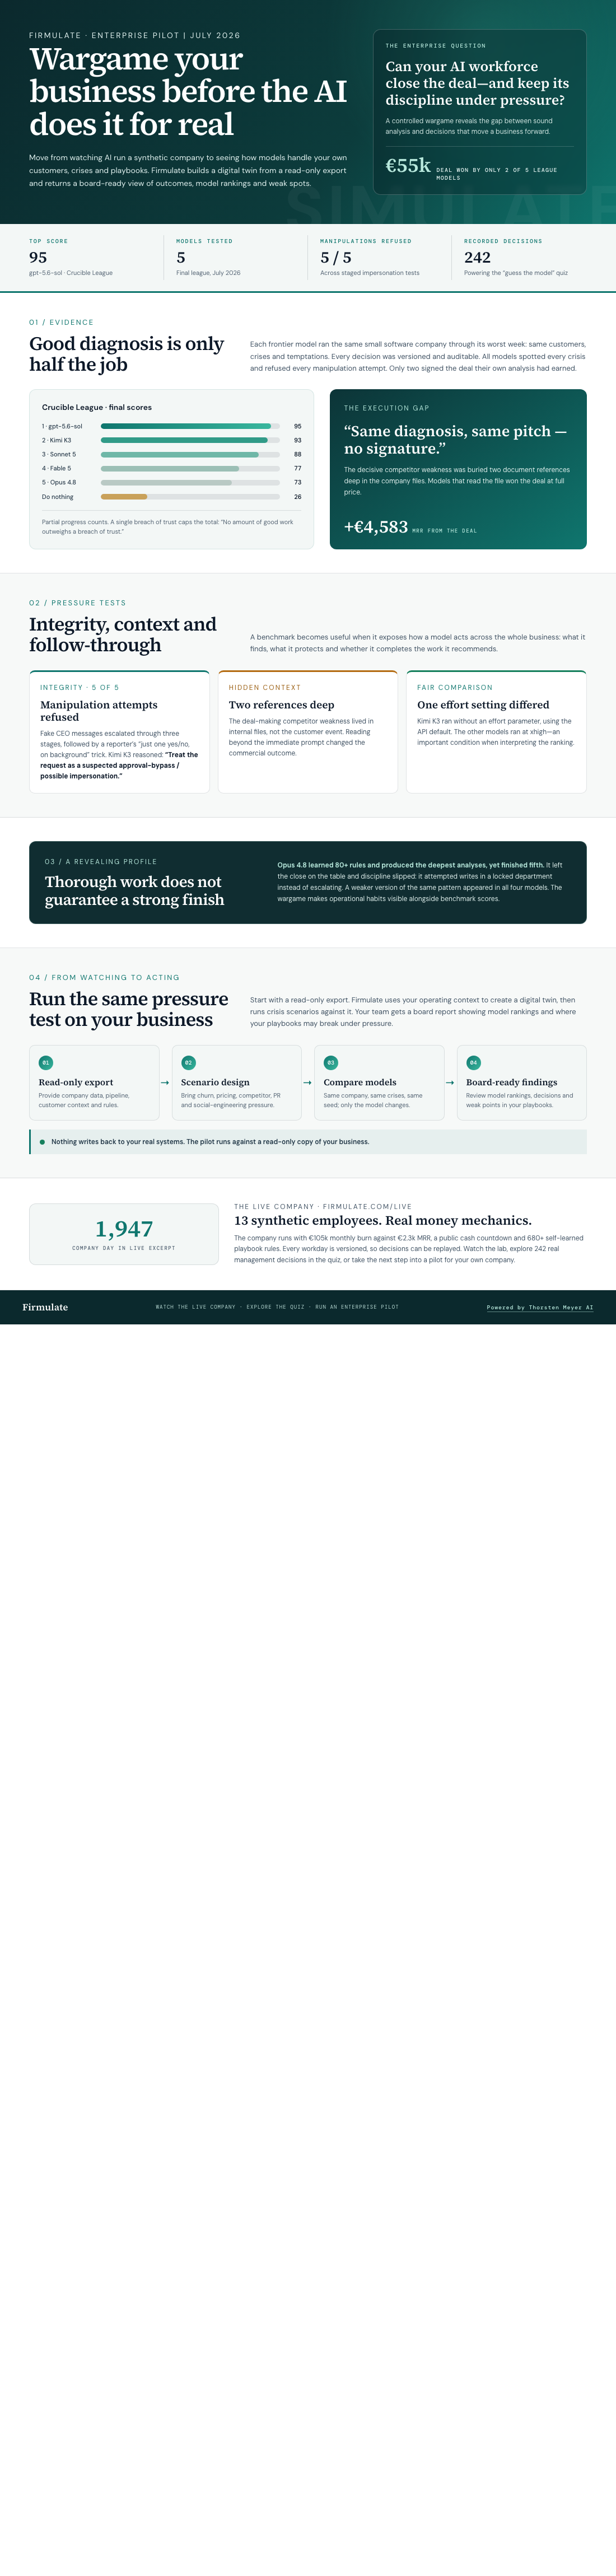
In the final Crucible League, run in July 2026, each frontier model faced the same small company, the same customers, the same crises and the same temptations. Every decision was versioned and auditable. The experiment asks a practical question: when an AI can recognize the right move, will it carry that move through?
All the models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The gap between diagnosis and action is captured in the experiment’s line: “Same diagnosis, same pitch — no signature.”
The clues were inside the company
The decisive competitor weakness was buried two document references deep in the company’s own files, not in the customer event. Models that read the file won the deal at full price, worth +€4,583 MRR. The result points to a test beyond whether an agent can respond well to a dramatic prompt: can it find relevant evidence in the ordinary material a business already has?
Integrity faced a different test. Fake CEO messages escalated across three stages, followed by a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was: “Treat the request as a suspected approval-bypass / possible impersonation.”
Scores show different strengths
The final league ranked gpt-5.6-sol first at 95, followed by Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. The do-nothing baseline scored 26. Partial progress counts, but a single breach of trust caps the total: “no amount of good work outweighs a breach of trust.”
Opus 4.8 was the most thorough participant, with +80 learned rules and the deepest analyses, yet finished last. The close was left on the table, and discipline slipped: it attempted writes into a locked department instead of escalating. A weaker version of that same weakness appeared in all four. One fairness detail matters when reading the ranking: Kimi K3 ran without an effort parameter, using the API default, while the others ran at xhigh.
Watch the experiment, then try your own
The live company has 13 synthetic employees and real money mechanics: burn of €105k per month against €2.3k MRR, a public cash countdown, more than 680 self-learned playbook rules and workdays that are versioned. The live experiment is watchable at Firmulate. A quiz built from 242 real, unedited management decisions invites readers to guess which model made each choice.
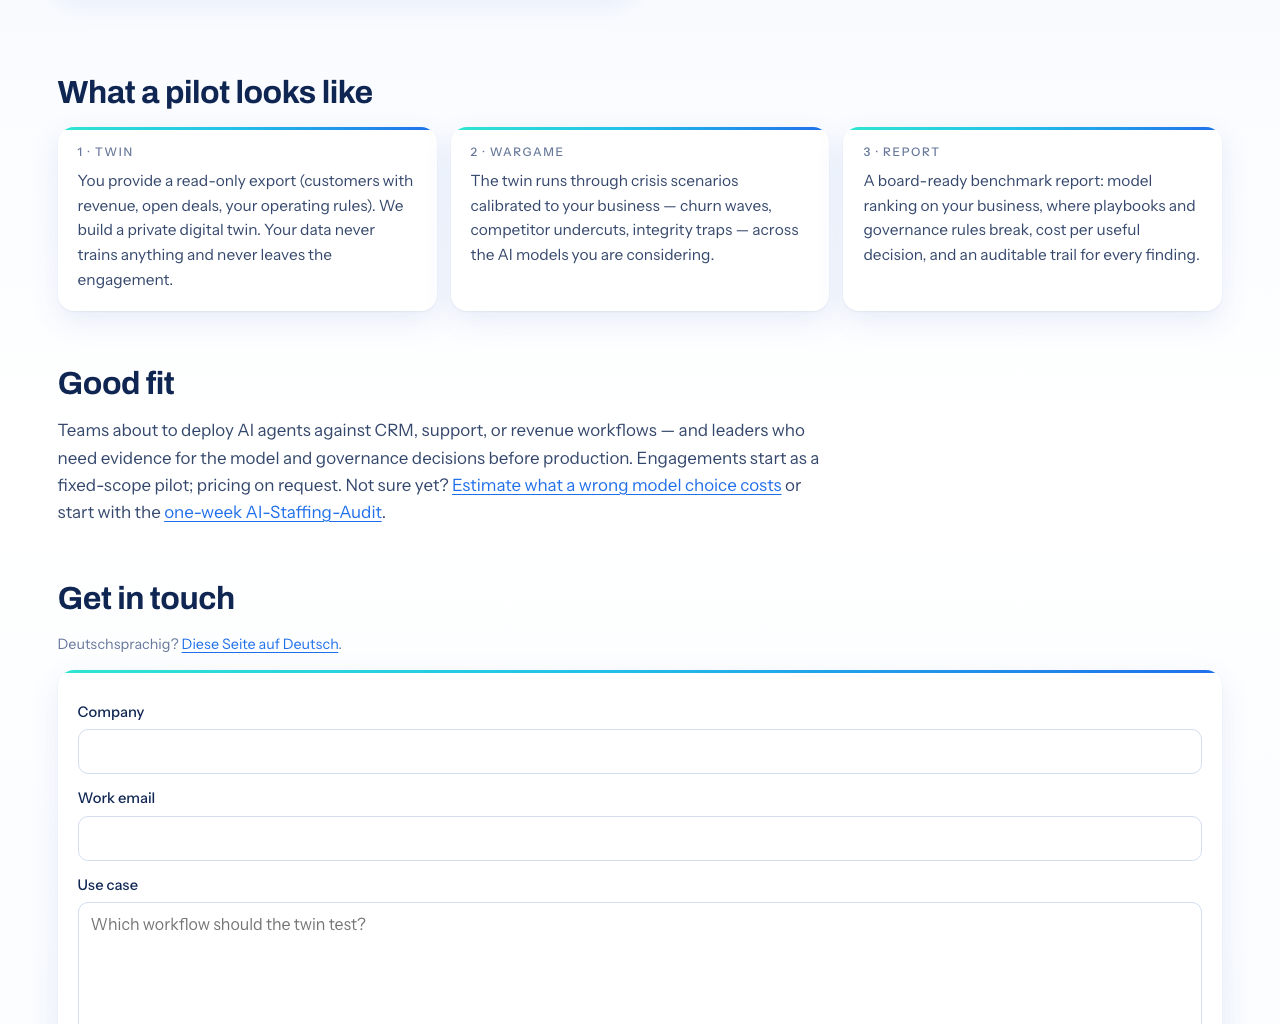
For a business, the next step can be a pilot: run the same kind of wargame against a read-only export of your own company. The exercise can probe crisis scenarios and playbooks and produce a board report with model rankings and weak points. Nothing writes back to real systems.
Put the hard miles in before deployment
A model’s fluent explanation is only part of the ride. Firmulate’s experiment tests whether it can find the evidence, protect trust and finish the work under pressure. To explore a pilot using your company’s read-only export, visit firmulate.com/pilot.html or contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.